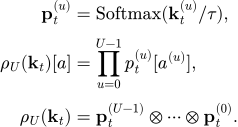Section 2 introduced the Address Decoder, which selects a small set of memory slots and assigns their weights.
The challenge is to make address selection itself efficient as memory grows, while keeping the key and query compact.
Product Softmax combines several low-dimensional distributions to assign weights to a much larger set of slots.
Definition and Calculation
First, write each integer slot address a as U base-dp digits, giving |𝒜| = dpU possible addresses.
Here, a(u) denotes the value at digit position u, one of 0, …, dp − 1; u = 0 is the least significant digit.
The key kt has dk = U dp dimensions.
Split it into U sub-vectors kt(u), each with dp entries.
Each sub-vector supplies scores for one address digit a(u), one score for each possible value.
The computation below turns each group into a digit distribution and combines them into slot weights. The query is decoded in the same way.
- Normalize each digit: apply a softmax to each sub-vector to obtain its digit distribution. The temperature τ > 0 controls how sharply each digit selects among its possible values.
- Multiply across digits: a slot's probability is the product of the probabilities of its digits. The complete distribution is the Kronecker product of the digit distributions.
- Keep only Top-K: the truncation operator 𝒯K retains the K largest probabilities and sets all others to zero, without renormalizing the retained weights. The key produces write weights; the query produces read weights.
The slot count |𝒜| = dpU grows exponentially with the number of digits U, while the key and query dimension dk = U dp grows only linearly, so U dp scores suffice to address all |𝒜| slots.
For example, |𝒜| = 1024 = 45 slots require only 20 scores.
Moreover, each digit distribution is shared by many slots, so a learning signal from a selected slot also updates the factors used by other addresses.
Below, we interpret Product Softmax from five different perspectives.
Soft Radix Address
This is the view used in the definition above: after softmax, each score group makes a soft choice for one address digit.
Each digit has dp possible values; combining one value from each of the U groups forms a complete address.
The product of those digit probabilities gives the weight of that address.
Multilevel Decision Tree
Addresses form a prefix tree: each node is a partial address, with dp branches for the next digit.
At each level, one score group supplies the branch probabilities, so multiple choices can carry weight simultaneously.
A complete path identifies one slot, weighted by the product of its branch probabilities.
Joint Distribution
Product Softmax defines a U-dimensional joint distribution, with dp possible values along each axis.
Each normalized score group supplies one axis's marginal distribution; multiplying these independent factors gives the probability at every grid point.
A peaked factor concentrates weight on a slice of the space; combining factors focuses it at the slices' intersections.
The figure shows U = dp = 4.
Regroupable Address
Several digits can be jointly encoded as one larger address digit: a group of m digits has dpm possible values.
Its distribution is the product of the original digit distributions, so regrouping changes the shape of the address space without changing any slot weight.
In the figure, three base-4 digits become one 64-way digit, yielding 64 × 4 and 4 × 64 views of the same slots.
Waveform Modulation
For any flat address a, the slot weight ρU(kt)[a] is the pointwise product of U sub-functions, where φ(u)(kt)[a] = pt(u)[a(u)].
As a runs through the slot array, wave u holds each value for dpu consecutive addresses and repeats every dpu + 1 addresses.
Low-order digits therefore produce short steps and fast cycles; higher-order digits produce longer plateaus and slower envelopes.
Soft radix describes digit choices; the prefix tree organizes their combinations; the joint distribution places them in U dimensions; regrouping combines digits into larger coordinates; and waveforms lay the factors out along the address axis.
These are five equivalent views of the same Product Softmax distribution, each useful in a different setting.
The tree view supports exact Top-K pruning: keep the K strongest prefixes at each level, evaluating at most K dp candidates per level without constructing the full slot distribution.
The joint view explains gradient broadcast: learning at one slot updates axis factors that are shared by many other slots.
The waveform view explains CAPE's shift equivalence: circularly shifting the full distribution is equivalent to shifting every factor waveform by the same amount before multiplying them.
 arXiv
 GitHub
 Hugging Face